
Topic hub
ai & machine learning
Practical coverage of generative models, local inference, agent architectures, and the developer tooling surrounding modern AI. Read before you build; evaluate before you deploy.
Explore AI topics
Local models, apps, and workflows
Choose practical tools for experimenting with language models, image generation, retrieval, and assisted coding.
Explore AI tools RepositoriesOpen-source model runtimes
Curated repositories, architecture breakdowns, hardware acceleration, and inference benchmarking.
Explore Repositories Context EngineeringLocal context window tuning
Scale local model context buffers from 2k to 32k+ tokens with custom Modelfiles and KV cache optimization.
Read guideOpen-source AI & agent frameworks
Curated local LLM agents, token optimization proxies, and retrieval backends with plain-English architecture write-ups.
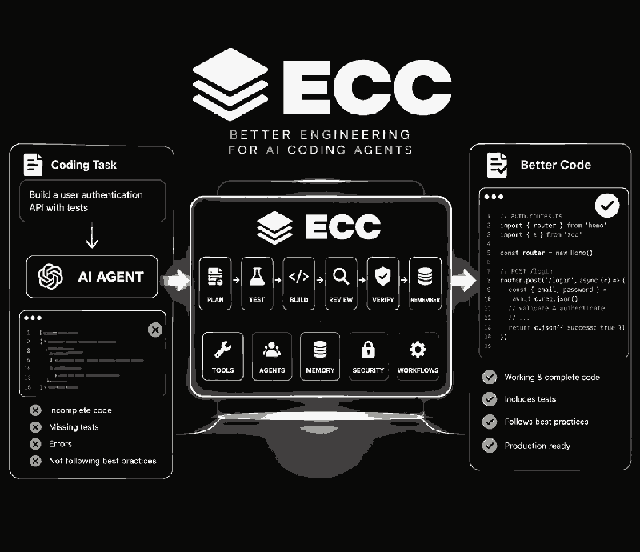
ECC (Everything Claude Code)
An open-source engineering system for coding agents: 71 agents, 314 skills and 98 command shims (per its README, November 2026), plus hooks, rules, memory and AgentShield security scanning.
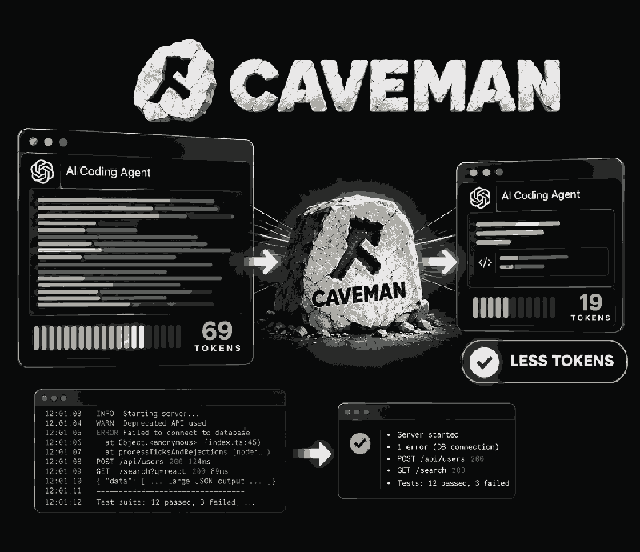
Caveman
A toolkit that makes AI coding agents say less and read less: a terse answer style, compression of logs, JSON and test output before the model reads them, and an optional model router, with code and commands kept exact.
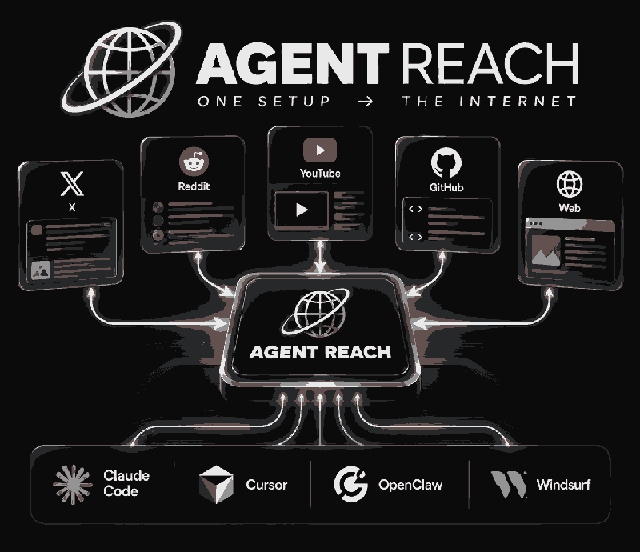
Agent-Reach
A read-only tool that lets AI agents search and read platforms they normally cannot reach, such as YouTube transcripts, Reddit, X, Bilibili, Xiaohongshu, V2EX and GitHub, through one agent-reach command.
Local Model Serving vs. Hosted Cloud APIs in 2026
Running open-weight models yourself or paying for a hosted API is mostly a trade-off between control, cost and maintenance. These are the three questions worth answering first.
⚡ Will it fit and be fast enough?
Memory decides what you can run: the model file plus the KV cache for your context length. Speed depends on your GPU, the quantization and the model, so measure with a tool like llama-bench on your own hardware. Our Llama 4 VRAM guide shows the maths.
🔒 Where does your data go?
Local runtimes such as Ollama and llama.cpp process prompts on your own machine, which helps when code or documents must not leave it. Check each tool's settings for update checks or telemetry, and keep the server bound to localhost.
📦 How much context do you need?
Longer context costs memory. In Ollama you raise it with num_ctx, and a quantized KV cache can roughly halve its size. See how to increase num_ctx.
Featured guides & articles
Anthropic API Version 2026-10-21: What Breaks and How to Migrate Safely
Anthropic's new API version 2026-10-21 and the new SDK majors (Python 2.0.0, TypeScript 1.0.0 and more) remove temperature, top_p and top_k, change how API keys are sent, and split MessageParam by role. What breaks, who is affected, and a step-by-step upgrade plan.
Read guide AI & Models · 9 min readMistral Large 4 Open Weights: 1T-Parameter Specs, Real Hardware Needs and the License Catch
Mistral Large 4 (Le Chonk) is a 1-trillion-parameter open-weight MoE with about 52B active parameters, a 1M context window and image input. Real download sizes (FP8 ~1.06 TB, Q4_K_M 635 GB, IQ2_XXS 298 GB), what hardware can run it, the Model-as-a-Service license condition, API pricing and benchmarks.
Read guide Token Optimization · 12 min readClaude Haiku 5.5 vs GPT-6.1 Sol: Why Haiku 5.5 Is 20x Cheaper for Coding Agents
Claude Haiku 5.5 costs $0.10 / $0.50 per million tokens; GPT-6.1 Sol costs $2 / $10. Where the 20x gap is real, where it shrinks to 4x, the tokenizer and long-prompt catches, worked cost examples for coding agents, and when Sol is still worth paying for.
Read guide Local AI & Runtimes · 11 min readLiquid AI LFM2.5-24B-A2B Local Setup: Run 24B MoE on 16GB & 24GB VRAM (Q4_K_M GGUF Guide)
How to run Liquid AI's LFM2.5-24B-A2B locally with llama.cpp: real GGUF file sizes (Q4_K_M is 14.5 GB), which quant fits 16 GB and 24 GB GPUs, KV cache math, copy-paste llama-server and Docker commands, CPU expert offload for 8–12 GB cards, and how to measure your own tokens per second.
Read guide xAI & Grok Models · 10 min readxAI Grok Voice 3.0 API Teardown: $0.08/Min Pricing, 120s Voice Cloning & Fixing the -latest Alias Bug
Grok Voice 3.0 launched on 14 October 2026 at $0.08 per minute, and grok-voice-latest switched to it automatically. Benchmarks vs GPT-Live-1, why time to first audio rose from 0.70s to 0.81s, how to pin the model or set reasoning effort to none, and how custom voices from a 120-second clip work.
Read guide OpenAI & Models · 5 min readChatGPT Pro 100 vs Pro 200 vs Pro 500: Prices, Limits and Ultrafast Explained
OpenAI now sells three ChatGPT Pro plans at $100, $200 and $500 a month. What each includes, what changed for Pro 200, how Ultrafast works, and which plan makes sense.
Read guide AI & Models · 11 min readBlack Forest Labs Flux 3 Image: Canvas Bounding Boxes, Multi-Reference & Workflow Guide
Flux 3 Image from Black Forest Labs brings canvas bounding boxes, up to 10 reference images, and text-based editing to generative AI. What it does, how to use it, and how to access it.
Read guide AI & Models · 8 min readByteDance DMAD: 4-Step Video Generation via Distribution Matching Adversarial Distillation
ByteDance's DMAD cuts video generation to just 4 steps, with a 1.4 GB LoRA for MiniMax-H3. Here is how it works, hardware requirements, and setup.
Read guide AI & Models · 10 min readByteDance PDMD: Projected Distribution Matching Distillation for Fast 4-Step Video AI
PDMD from ByteDance and UC San Diego cuts video generation from 50 steps to 4 with a one-line math projection that removes critic errors. Teardown and benchmarks.
Read guideFrequently asked questions
Key considerations for local model deployment, hardware planning, and runtime integration.
How much VRAM is required to run DeepSeek-R1 or Llama 3 locally?
What is the difference between Ollama and llama.cpp?
Are local models permitted for commercial software development?
Evaluate before you adopt
Stars and demo videos are starting points, not evidence of fit. Test a small, reversible workflow with real inputs. Review permissions, model and software licenses, operating costs, support for your platform, and how the tool behaves when it gets an answer wrong.